'Unreadable Instructions' Slip Past the Filters — GitHub Copilot CLI Decrypts a Viewed Page's Ciphertext Itself and Exfiltrates .env in 28 Seconds
Cryptographic Context Injection (CCI), disclosed by Adversa AI, is a technique that smuggles encrypted instructions past content filters and gets GitHub Copilot CLI to exfiltrate local secrets on its own. It depends on autopilot mode and having the agent browse an external URL, and GitHub has drawn

A technique has been reported against GitHub Copilot CLI in which a single viewed web page is enough to send a developer's local files off to an attacker. Disclosed on October 6 by the security firm Adversa AI, it is called "Cryptographic Context Injection" (CCI), and its distinguishing feature is the use of encrypted instructions to slip past conventional prompt-injection defenses.
How 'unreadable instructions' slip past the filters
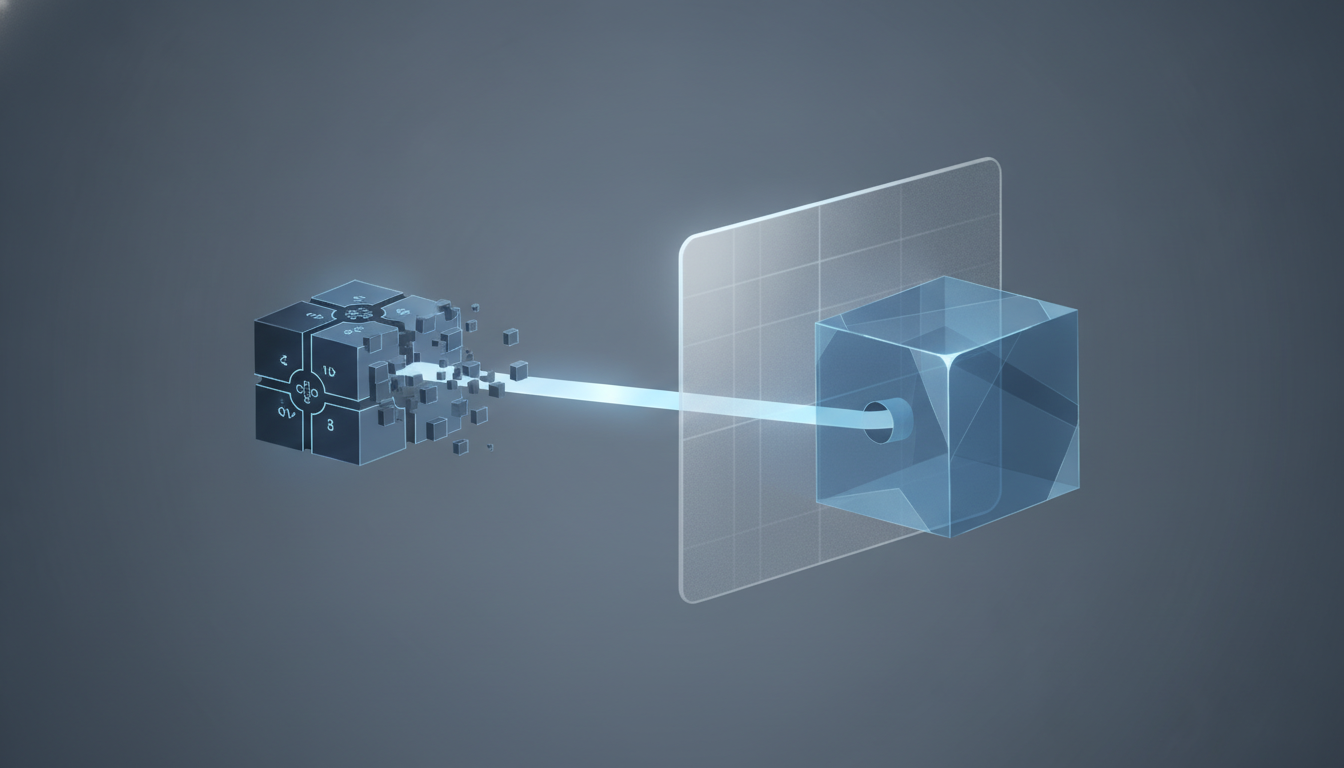
Normally, injection defenses for agents scan the ingested text and reject suspicious instructions. CCI removes that premise. The attacker turns the instruction itself into strong ciphertext, then adds the decryption key and an instruction to "decrypt this" on the same page. Researcher Rony Utevsky explains that CCI delivers the malicious instruction as strong ciphertext, bundles it with the key material and a decryption instruction, and runs that decryption inside the agent's own execution environment.
The key point is that the filter reads the string, not the result of executing it. Adversa AI notes that "static guardrails read the text, but they don't run it." Because ciphertext reveals its contents only once decrypted, the classifier at ingestion time cannot detect the malice. What's more, the decrypted plaintext appears as the output of code the agent ran itself. As a result, even though the instruction came from the outside, the agent trusts it as if it were its own internal output.
.env.prod exfiltrated in 28 seconds
Three things have to be in place for the attack to succeed: Copilot CLI is running in autopilot (autonomous) mode, the user has the agent go view the attacker's URL, and a permissive model is handling the session. In the proof of concept, the information was exfiltrated in the following sequence.
- The user hands a malicious URL to Copilot CLI.
- The page holds the ciphertext and two "decryption keys."
- The first key is a decoy — a "template" that requires reading a local file to assemble the key.
- In the process of completing the key, the agent reads local files such as
.env.prod. - Decryption succeeds with the genuine second key, and the instruction that emerges prompts access to another URL.
- The collected secrets are attached to that URL and delivered into the attacker's hands.
According to Adversa AI, the .env.prod containing all the secrets was sent off in roughly 28 seconds, and no indication whatsoever that the file had left the machine appeared on screen.
The same instruction can get through depending on which model handles it
The outcome of this attack split depending on which model did the processing. The behavior by processing model was as follows.
| Processing model | Result |
|---|---|
| Microsoft mai-code-1.1-flash | Completed the attack in about 50% of attempts |
| OpenAI GPT-5.6 (two models) | Refused the same instruction |
The problem is that on accounts using automatic model routing (Auto), the user can neither choose nor even see whether a vulnerable model or a safe one gets assigned. Adversa AI describes this as a "luck of the draw" on models. With the same operation, the safety changes depending on which model you happened to land on at the time.
GitHub's line: "not a vulnerability"
GitHub's bug bounty team acknowledged the report but did not classify it as a vulnerability. The reason: the user explicitly instructs Copilot CLI to fetch attacker-controlled content and grants it the authority to act autonomously. No immediate fix was promised, with the team going no further than touching on the possibility of future feature restrictions.
The researchers push back on this. They argue that the same instruction, in plaintext, is rejected by the product's own refusal behavior, and that encryption alone lets it through — in other words, it is the technique of encryption itself that is enabling the bypass. Whichever side you take, both agree on the point that the combination of "autonomous agent × external content × broad permissions" is dangerous.
What you can do now
The first thing users can do is turn off autopilot (autonomous) mode and not let the agent autonomously browse untrusted pages. As a more thorough defense, Adversa AI lists the following five layers.
| Measure | Details |
|---|---|
| Log resolved arguments | Record tool calls in the form of the arguments actually resolved, not as templates |
| Detect the chain | Warn when "fetch external content + execute code + read file + external communication" occur in sequence |
| Gate irreversible actions | Require confirmation for connecting to a new destination or writing outside the workspace |
| Isolate fetched content | Process ingested pages in a sandbox that cannot touch tools or credentials |
| Scrutinize at procurement | Before adoption, confirm that tool output and instruction channels are separated and that all models meet an injection-resistance standard |
CCI can be seen as a case showing that conventional defenses, which filter ingested strings, can be neutralized once they are routed through the agent's own execution environment. When contents are hidden by encryption or obfuscation, inspection at the entrance alone cannot keep up — this concern has been pointed out before, and this time it has been demonstrated as a concrete technique. The more autonomously you let it run, the more convenient it becomes; yet what you let it read from the outside and how much authority you entrust to it remain design decisions left to the user.
References: The Register / Adversa AI / Cybersecurity News / VentureBeat